Yao Tang 唐尧

Ph.D. Student, Computer and Information Science, University of Pennsylvania

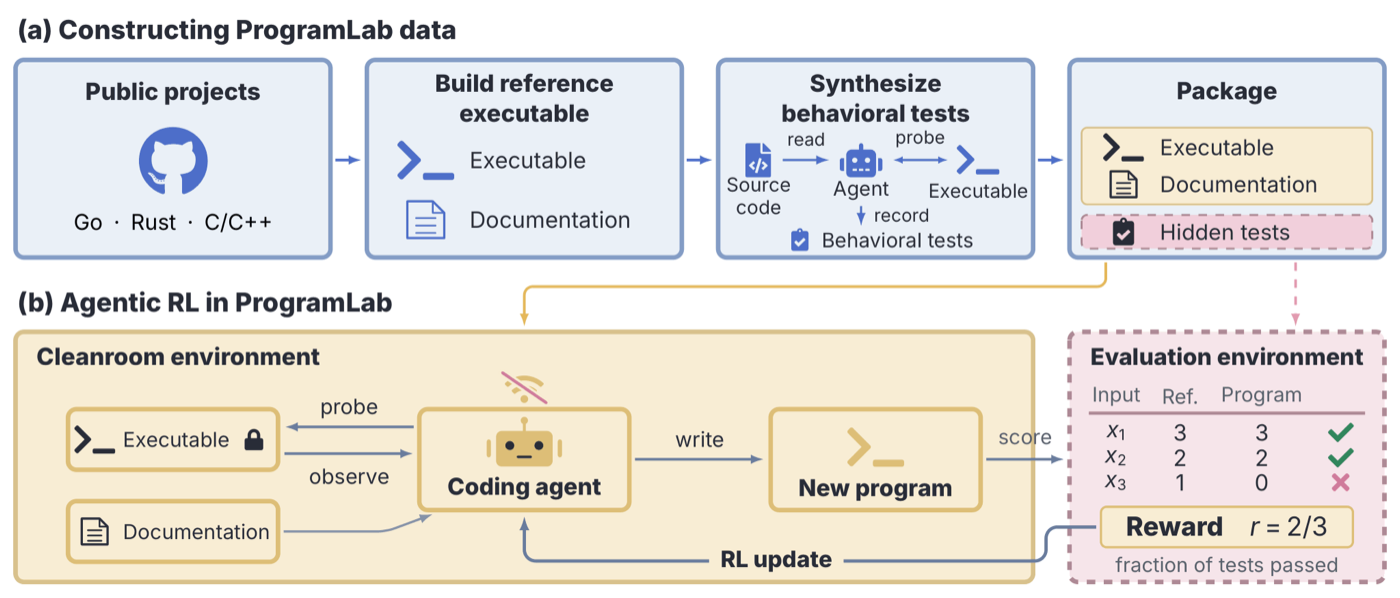
Hi there! I am a second-year Ph.D. student at Penn, advised by Prof. Jiatao Gu. I work on agentic reasoning and reinforcement learning: designing new reasoning paradigms that can be trained with RL at scale (Multiplex Thinking, RPT), and building scalable environments and rewards for long-horizon agentic tasks (ProgramLab, QLASS).

Before Penn, I received my B.Eng. from Shanghai Jiao Tong University and worked with Dr. Li Dong at MSRA and Prof. Kai-Wei Chang at UCLA.

Photo of Yao Tang

News

Selected Publications

ProgramLab overview
ProgramLab: Train Single and Multi Agents to Rebuild Programs with RL
Yao Tang+, Daixuan Cheng+, Li Dong, Zhihao Zhan, Shaohan Huang, Jiatao Gu, Furu Wei (+core contributor)
Blog Post, 2026
Multiplex Thinking overview
Multiplex Thinking: Reasoning via Token-wise Branch-and-Merge
Yao Tang, Li Dong, Yaru Hao, Qingxiu Dong, Furu Wei, Jiatao Gu
Preprint, 2026
Reinforcement Pre-Training overview
Reinforcement Pre-Training
Qingxiu Dong*, Li Dong*, Yao Tang, Tianzhu Ye, Yutao Sun, Zhifang Sui, Furu Wei (*equal contribution)
Preprint, 2025
QLASS overview
QLASS: Boosting Language Agent Inference via Q-Guided Stepwise Search
Zongyu Lin*, Yao Tang*, Xingcheng Yao*, Da Yin*, Ziniu Hu, Yizhou Sun, Kai-Wei Chang (*equal contribution)
ICML 2025
CurrMask overview
Learning Versatile Skills with Curriculum Masking
Yao Tang*, Zhihui Xie*, Zichuan Lin, Deheng Ye, Shuai Li (*equal contribution)
NeurIPS 2024

Experience

Misc.

I enjoy jazz dance and am a beginner at guitar. I am a big fan of David Tao.

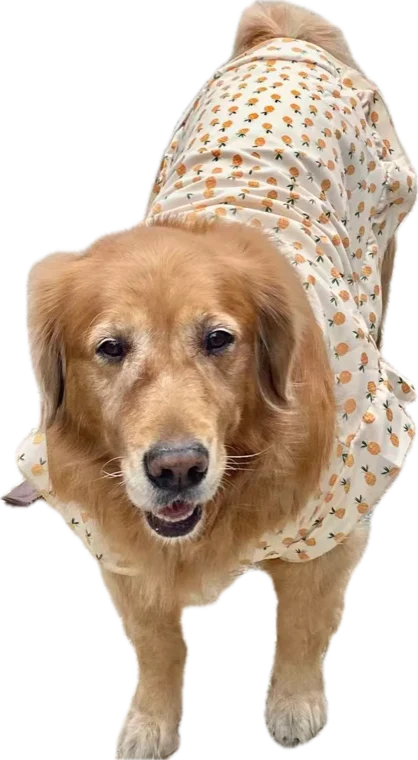
My family dogs Yibu and Happy love to play with humans through RL. After dynamic sampling, Yibu's training batch size is only 2 (sit and turn around), so we show Happy's checkpoint below.

🐶 Happy's RL checkpoint at 3 months old
🧋 My dream Boba-Agent

I am interested in building generalized AI agents under limited supervision. Take developing a 🧋Boba-Agent that can make all kinds of boba as an example.

🤔To train a Boba-Agent, the most straightforward way is to collect a bunch of boba expert demos and train the agent via imitation learning. But data collection is too costly and the model can poorly generalize to making 🥭mango pomelo sago if the data is on 🍋lemon tea.

🤔Another choice is to allow the Boba-Agent learning from a large amount of trial-and-errors. The agent can keep exploring the kitchen, making different boba, receiving my reward, and improving its boba-making policy via reinforcement learning. Unfortunately, this process is friendly for neither me nor the kitchen.

πŸ˜€The ideal case is that the agent can firstly search online and learn from offline video demos and textual instructions, extract reusable knowledge, and learn to safely navigate the kitchen, and quickly adapt to personal preferences. (For instance, learning that my highest praise is reserved for boba that's "not too sweet"!)

To summarize, my interests lie in how to enable effective internal world modeling to help the agent learn from large-scale boba-making offline data and extract reusable knowledge, as well as external world interaction, e.g., searching for new recipes online, exploring the kitchen, and getting feedback from me, so that it can quickly make delicious newly invented Boba under limited supervision.
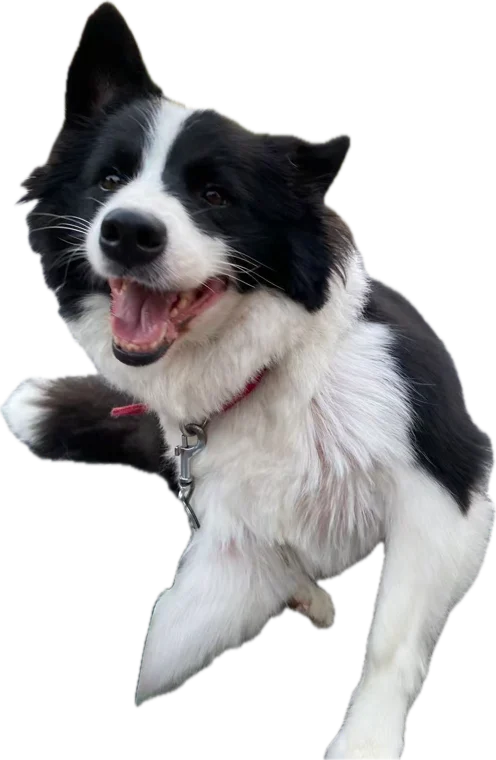
Happy, a border collie
Happy
Yibu, a golden retriever in a pineapple shirt
Yibu